
DreamX: Video Diffusion Model is a Universal Latent Action Learner
Source: alphaxiv.org
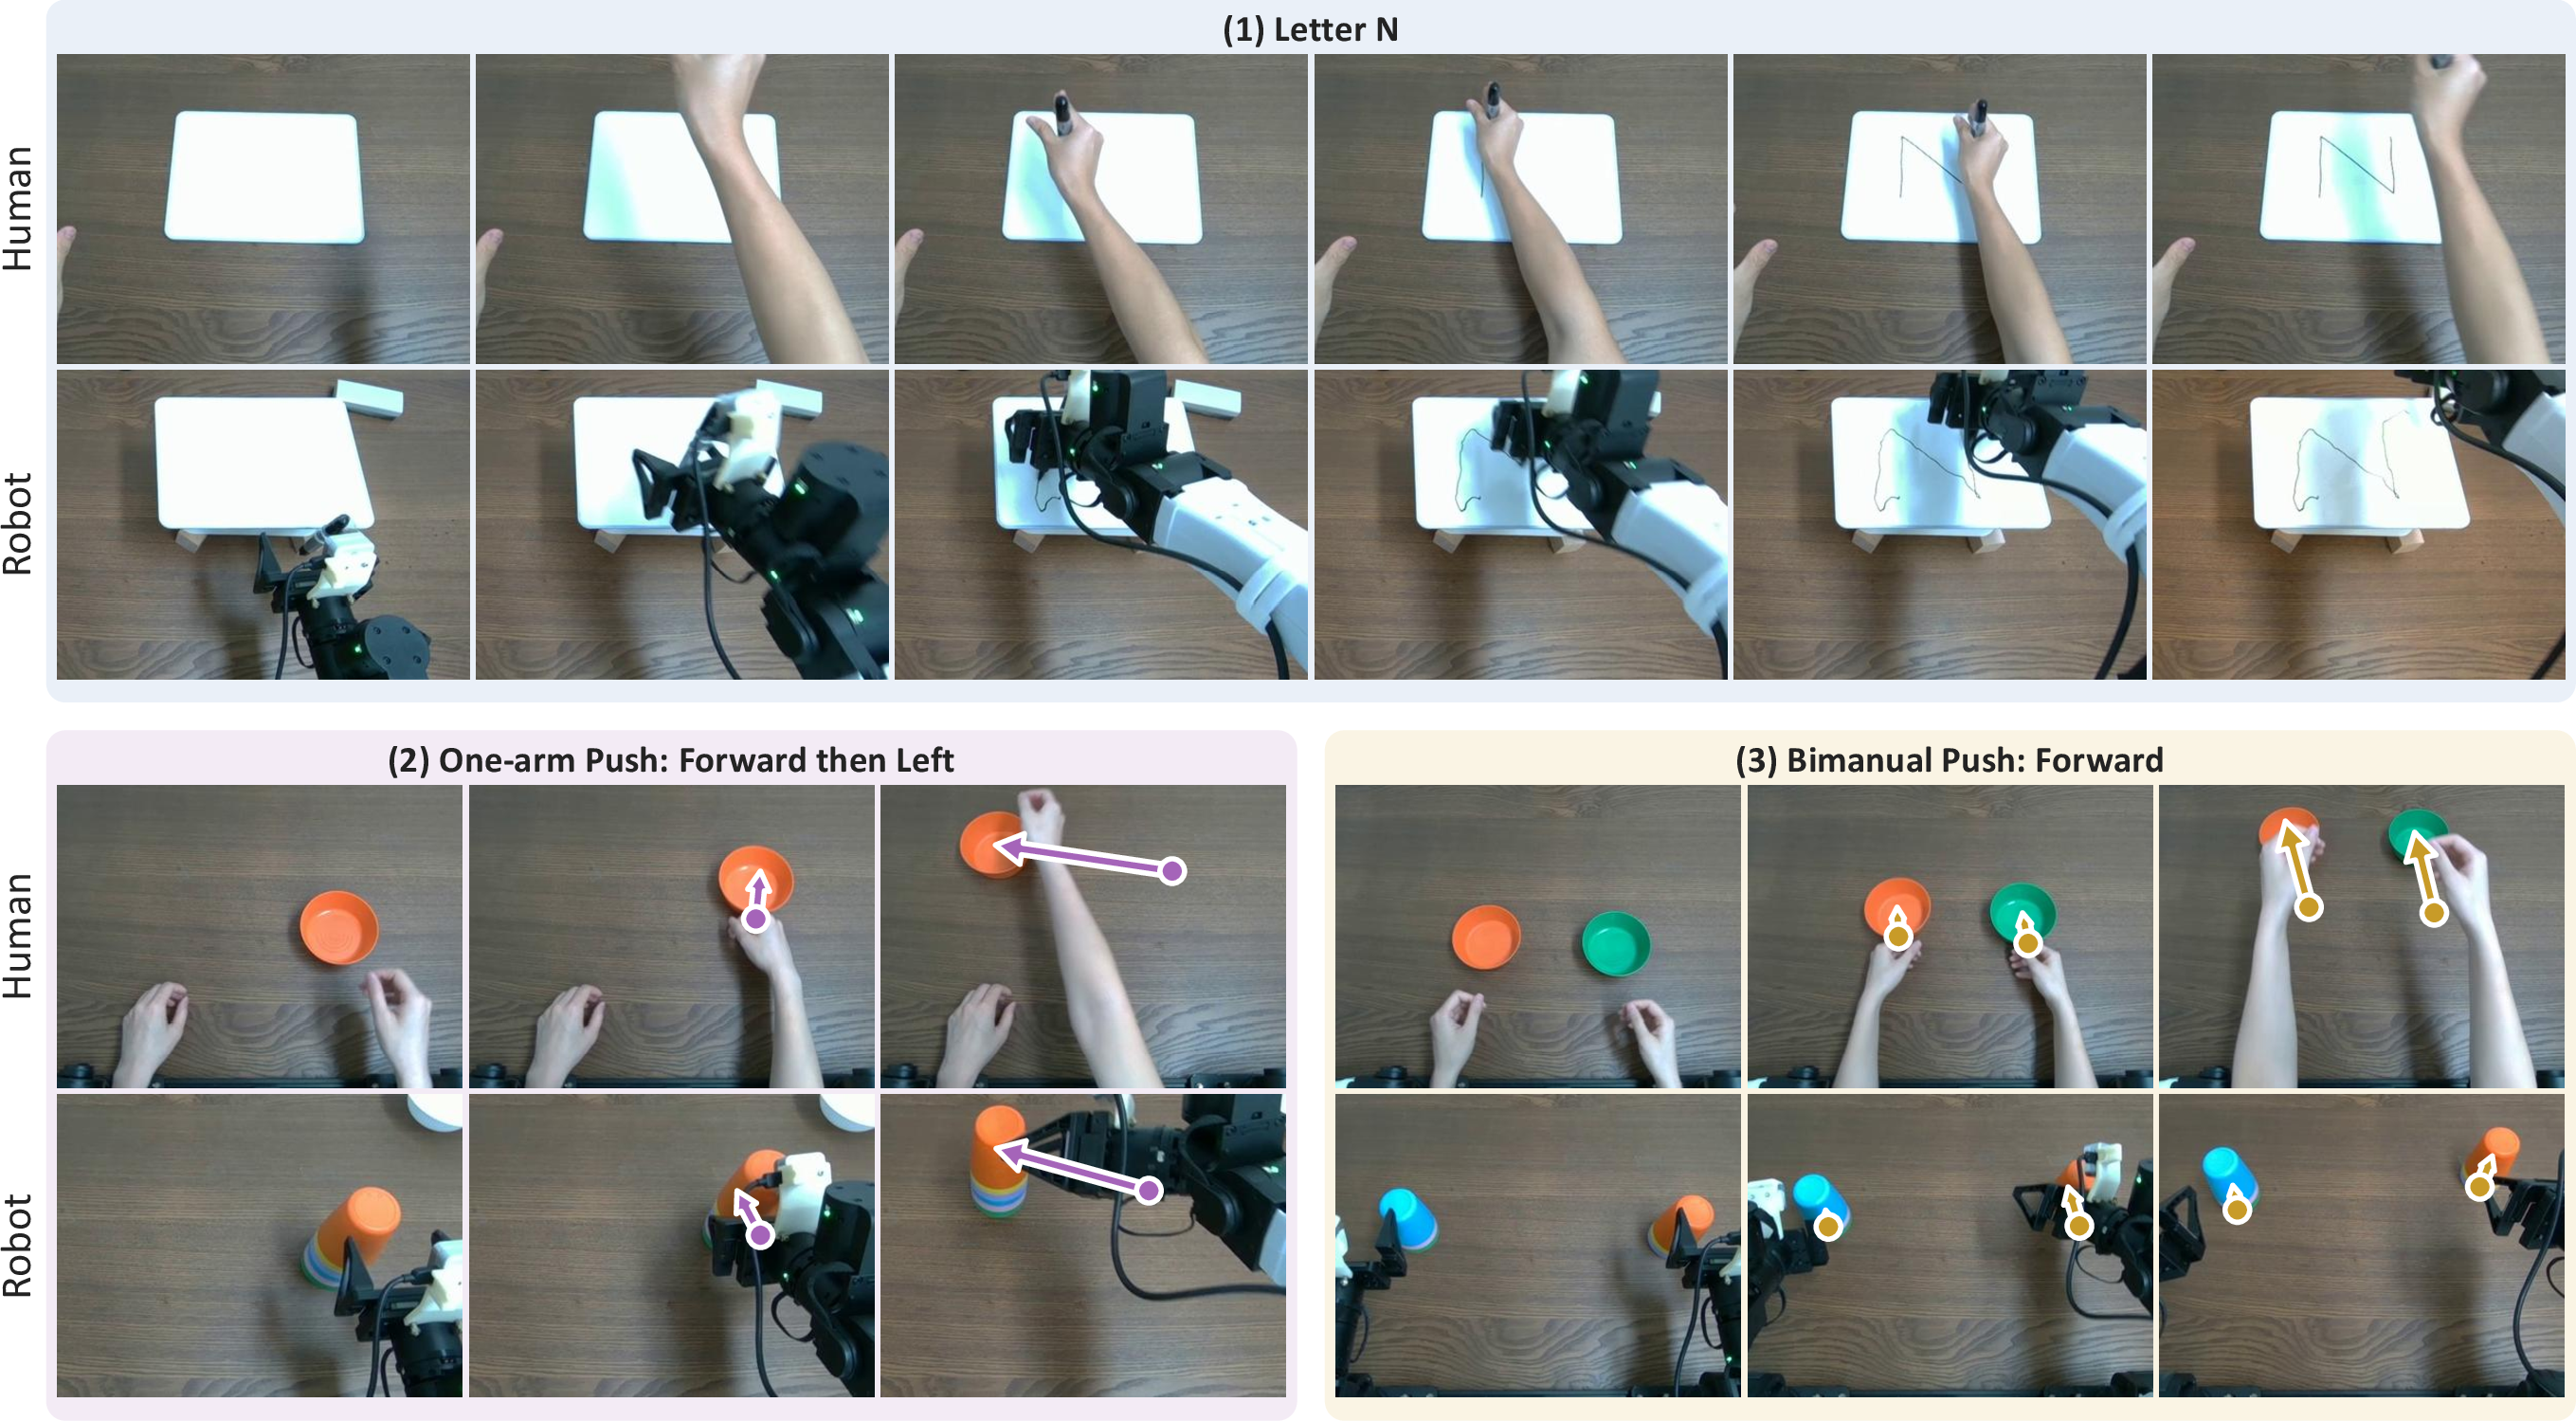
DreamX, a video diffusion model adapted to act as a universal latent action learner, addresses the lack of labeled robot actions and differing robot control languages in human videos by having a pretrained video generator summarize observed motion into a small code used to produce motion in a different setting. In real-robot demonstrations, a human writes the letter "N" and the robot reproduces the stroke pattern with no paired human–robot training data, shown with open-loop execution without visual feedback. DreamX uses learnable query tokens that read spatiotemporal features from a clip, with a decoder reconstructing future frames from those queries plus the initial frame; the compact summary is the latent action. Four query tokens summarize 1,200 video tokens per latent frame, a 300× reduction in token count. On LARYBench, with frozen representations and a common attentive probe, DreamX's normalized action MSE is 0.17 versus 0.38 for DiLA, and its classification accuracy is 69.67% versus 62.25%, averaged over the specified datasets and settings.
SUCKS 0
0
0
Comments
This page shows all existing comments. To add a new comment, open the post in the forum.
No comments yet.