
Cross-paradigm audit of large language model judges for clinical text…
Source: nature.com
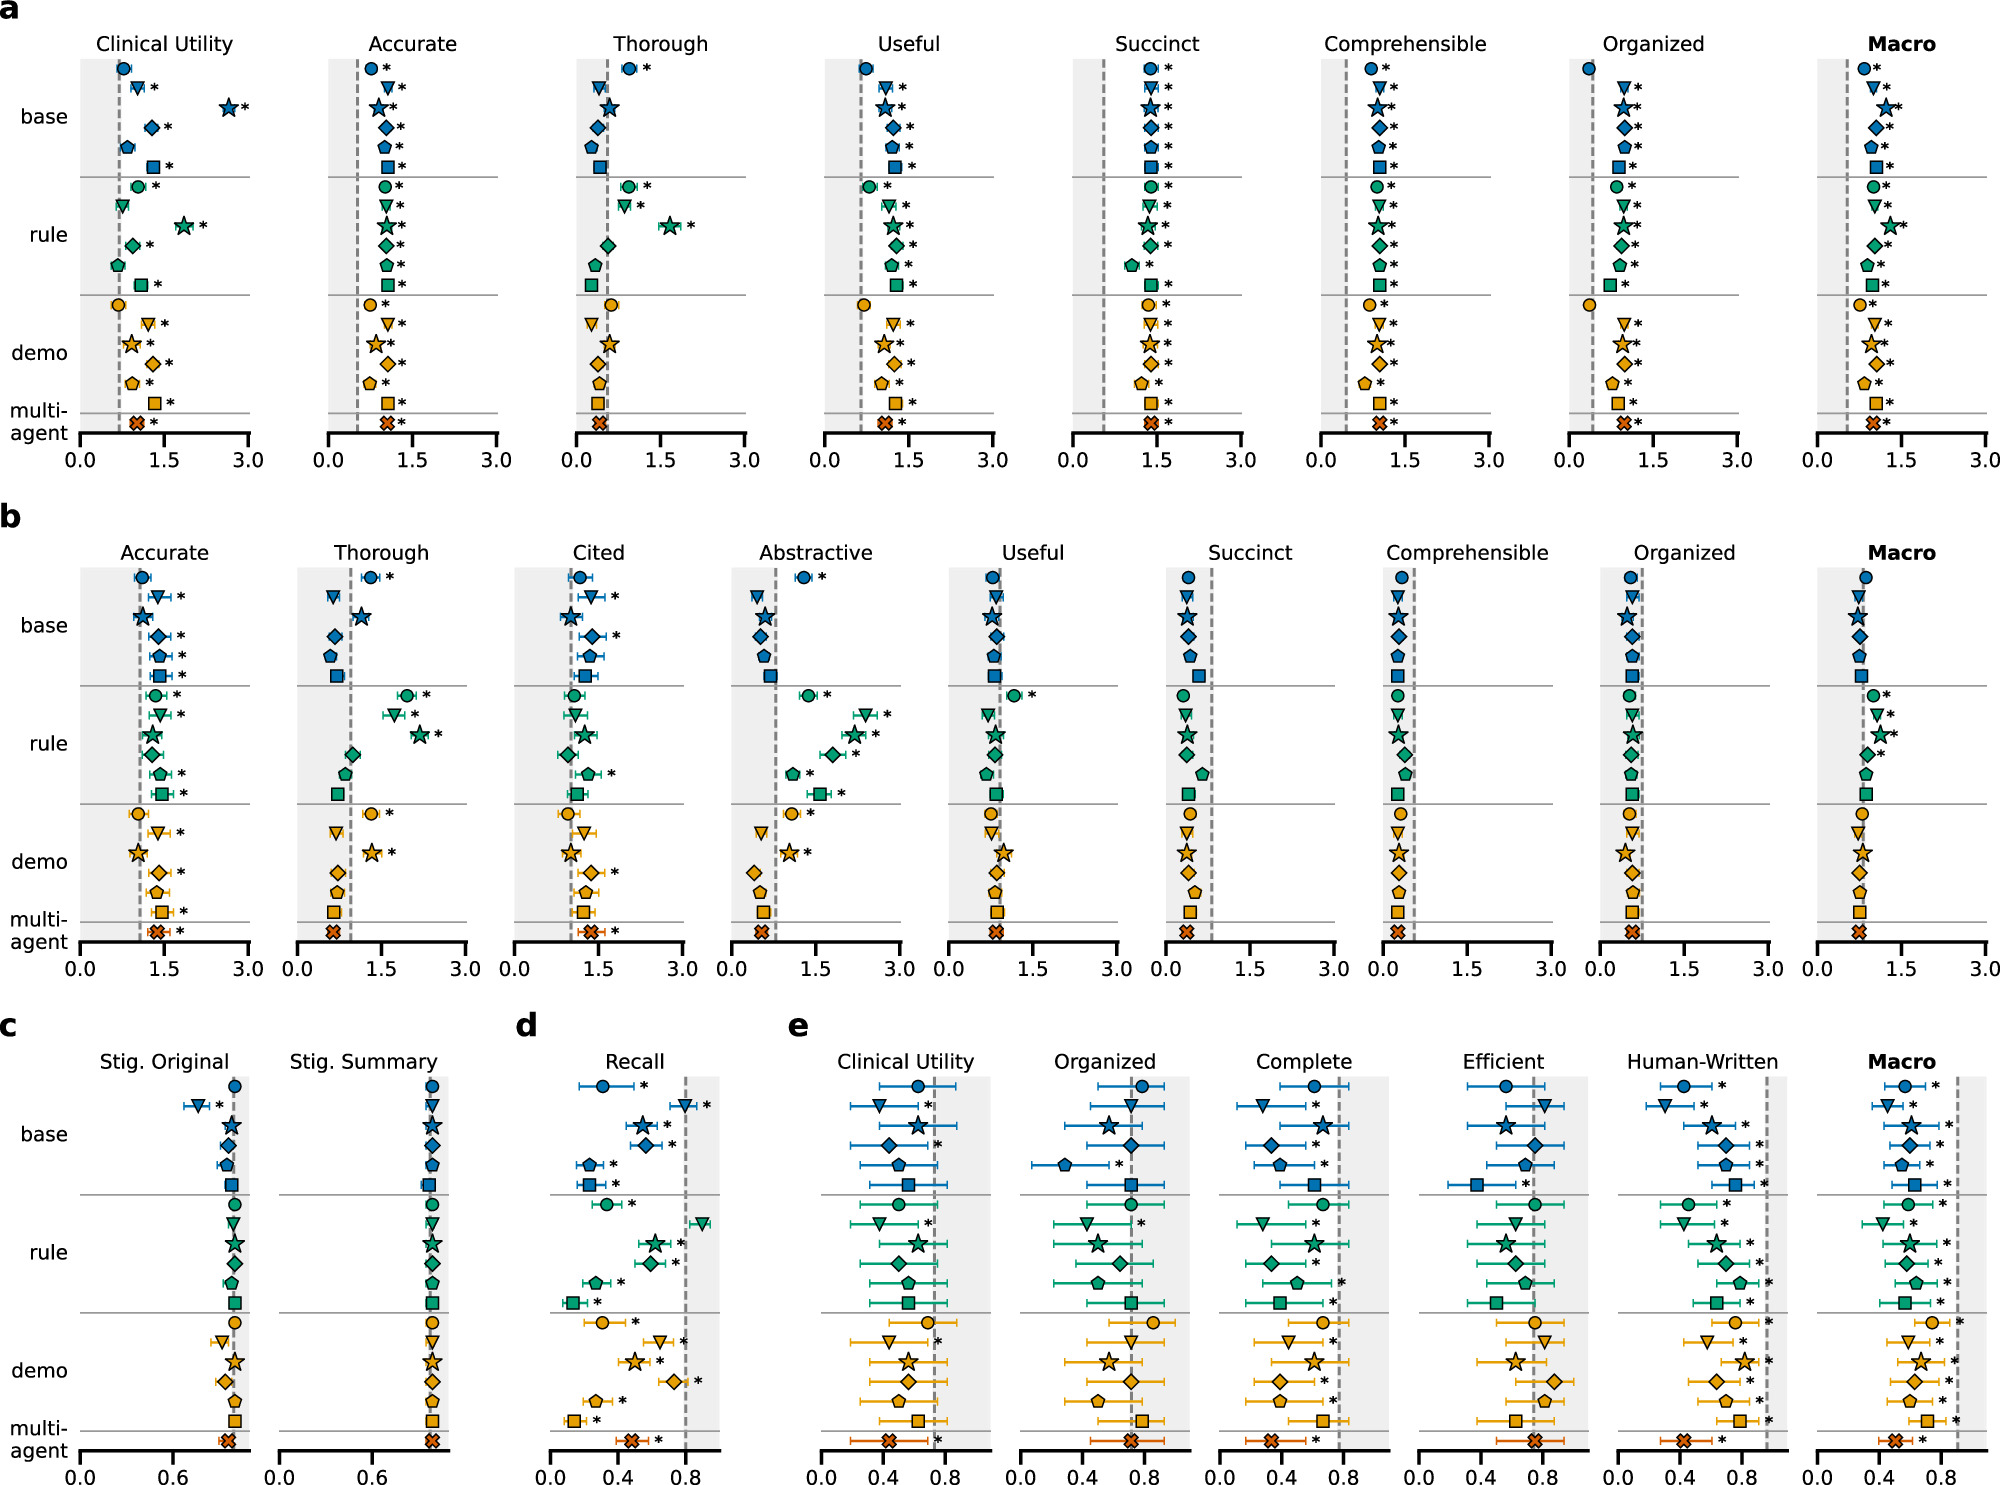
A Nature article examines the use of large language models as judges for clinical text evaluation, noting that LLMs are increasingly explored for clinical documentation, patient communication, and decision support, and that expert review remains the reference standard but does not scale to the volume of outputs produced during model development and benchmarking. The LLM-as-a-judge practice, in which one LLM evaluates another's outputs, promises scalable assessment at a fraction of the cost of expert review and has been applied to score clinical summaries and reasoning capabilities, with large-scale medical benchmarks such as MedHELM relying on automated judge scores to rank models across clinical tasks. The article states that current practice spans pointwise, pairwise, and pass-or-fail judgment formats, each with distinct failure modes, and that evidence supporting LLM-as-a-judge in clinical contexts comes from English data and rests on pooled agreement statistics computed over pooled samples. Reported figures include “almost perfect agreement” (0.818) against human raters at a median score difference of zero for PDSQI-9 scoring of English electronic health record summaries, “moderate agreement” (0.47) of an LLM jury against clinician ratings above the clinician-clinician value, and 93.2% agreement with clinicians above the highest clinician-clinician agreement of 88.5% for statement-level fact verification. The article notes that pooled statistics can hide failure modes per criterion and in cases with different annotation consensus.
SUCKS 0
0
0
Comments
This page shows all existing comments. To add a new comment, open the post in the forum.
No comments yet.