
Hidden flaws in AI training data threaten the future of software auto…
Source: eurekalert.org
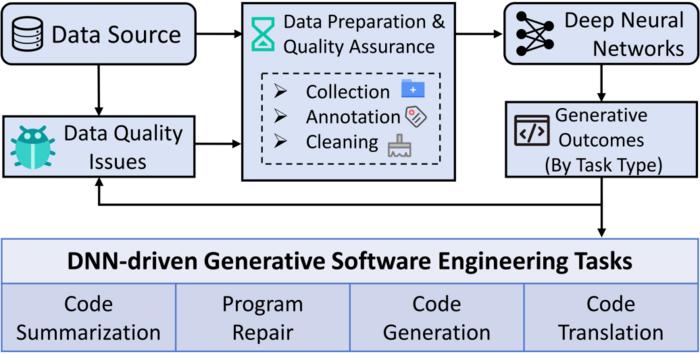
A systematic literature review from Nanjing University, published on 15 September 2026 in Frontiers of Computer Science, has found that many AI models used for software development may be built on low-quality training data. The study is the first to focus on data preparation and quality issues in code-centric generative software engineering tasks (GSETs), such as code summarization, generation, repair, and translation. The research team analyzed 70 studies and found widespread flaws in the datasets powering these models, including noisy or outdated code, lack of diversity, imbalanced samples, and inconsistent annotations, which significantly impact the accuracy, generalization, and reliability of AI tools increasingly used by developers. “Without high-quality data, even the most advanced models can’t perform well,” said Yang Feng, corresponding author of the study. Most datasets are collected automatically from platforms like GitHub or StackOverflow, often without proper cleaning or validation, while manual annotation is rare but more accurate. Many benchmarks are outdated, and some may have leaked into the training sets of large language models, inflating evaluation results, while programming languages like Ruby and JavaScript are underrepresented. The study highlights proposed strategies including automated data cleaning tools, data augmentation methods (e.g., back-translation and code mutation), multilingual training techniques, and improved dataset design standards, though these solutions are sporadic and rarely applied consistently across tasks. The authors call for a shift from model-centric to data-centric development in AI for software engineering.
SUCKS 0
0
0
Comments
This page shows all existing comments. To add a new comment, open the post in the forum.
No comments yet.