
SpecOPD: Branch-Parallel On-Policy Distillation for Speculative Decod…
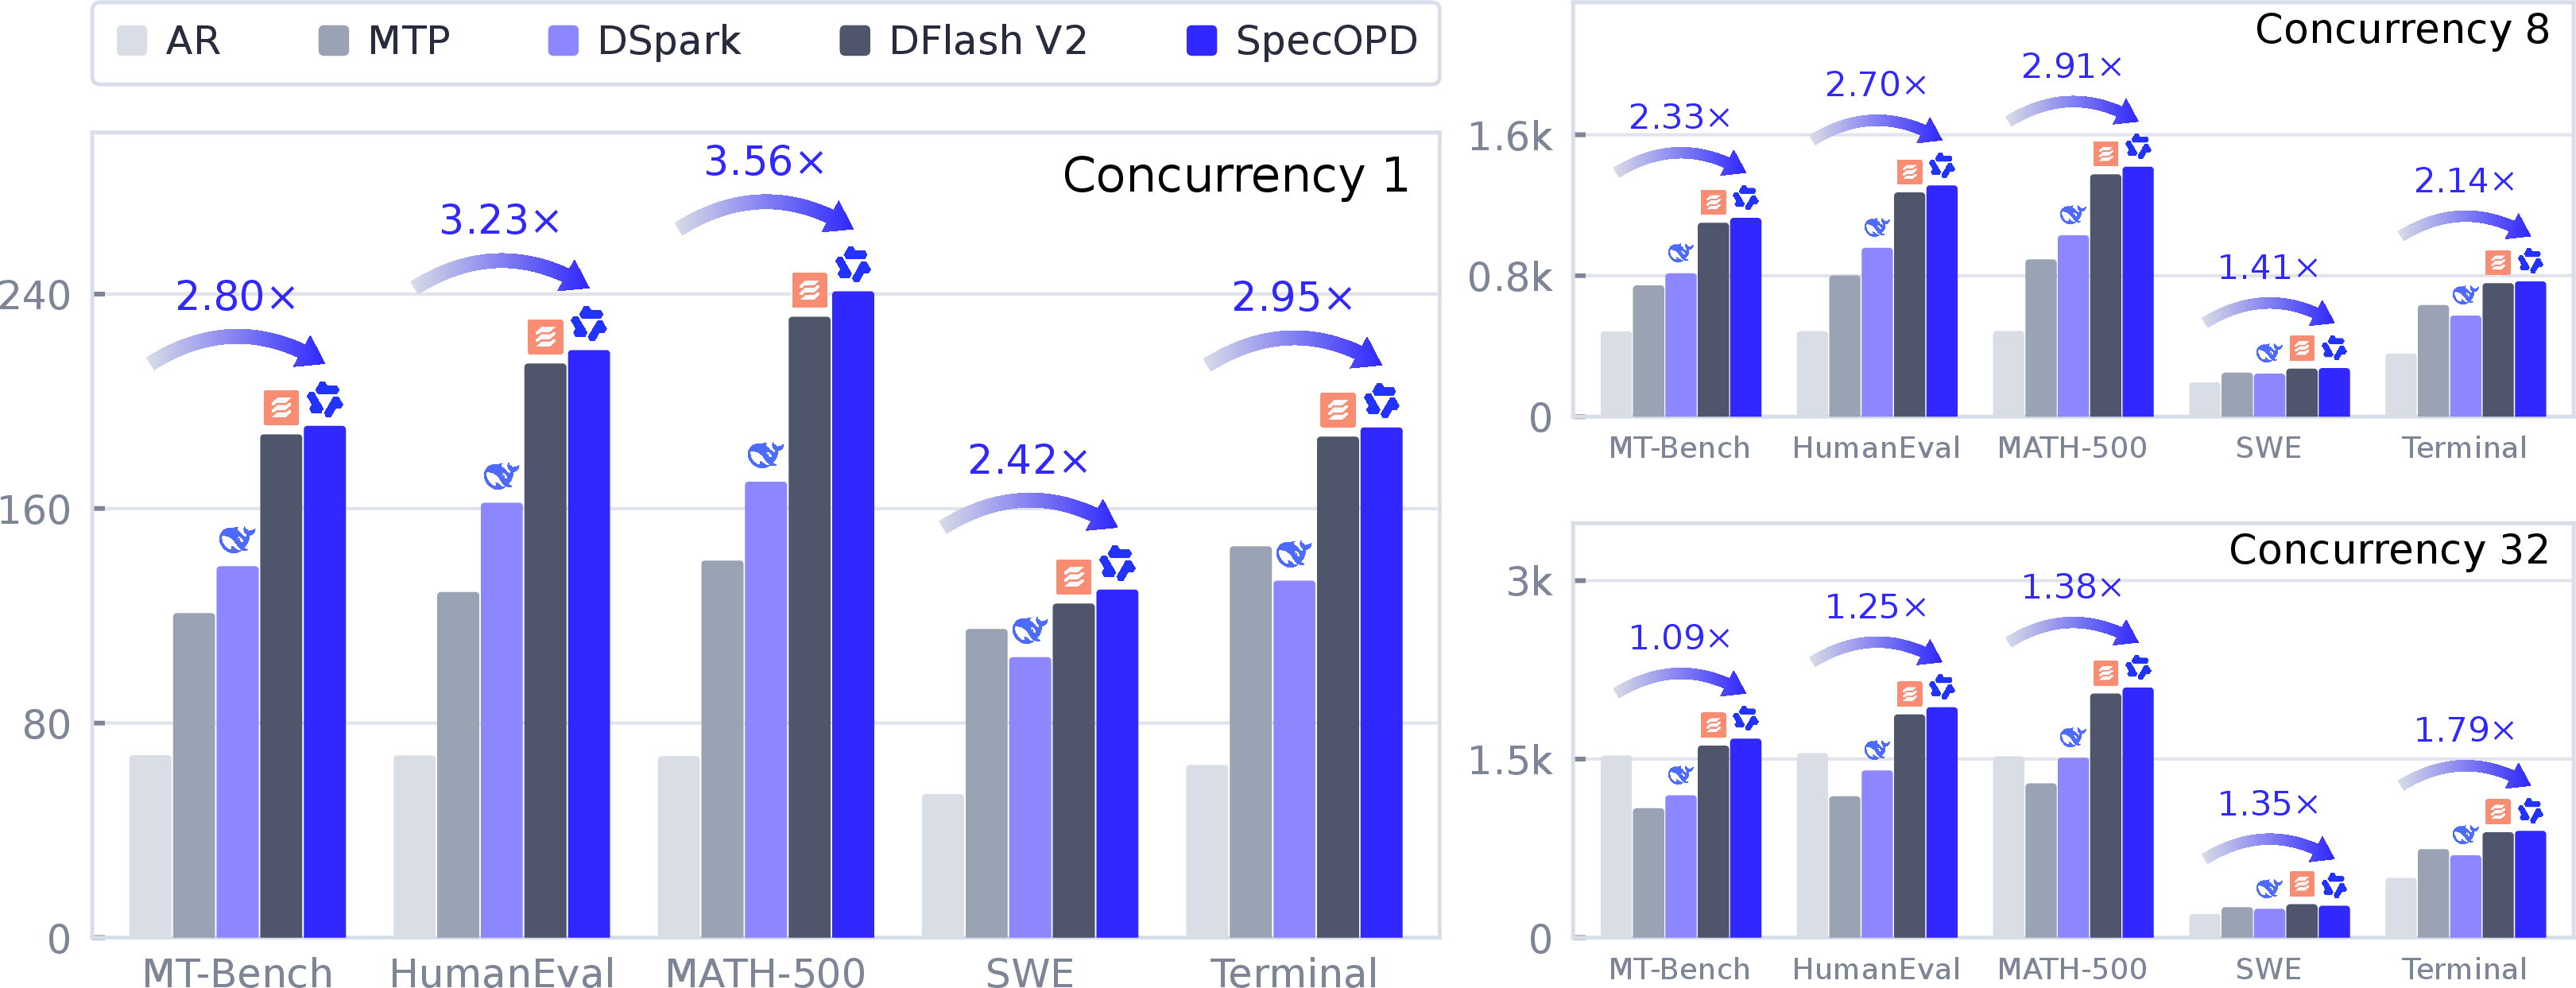
Source: alphaxiv.org
SpecOPD introduces a branch-parallel approach to on-policy distillation for speculative decoding, according to the article. Speculative decoding uses a small drafter to propose a block of tokens that a large target model verifies in parallel, but the payoff depends on how much of each block survives verification. Training a drafter on its own suggestions (on-policy distillation) should help, but the usual method collects examples by waiting through successive draft-and-verify rounds. SpecOPD instead branches from several fixed places in existing reference text and supervises each branch on its own freshly sampled history, sharing computation for their common prefix. It keeps a pre-collected reference response as a shared outer context, samples anchor positions on it, and samples fresh draft continuations from the current drafter at each anchor. Branches do not depend on one another's verification outcomes, though tokens within a branch remain sequentially dependent. "On-policy" here means fresh samples from the current drafter at fixed reference contexts, not unrestricted full-response rollouts. The reference data are still needed; what disappears is the sequential collection of full verified trajectories during training. The closest predecessor, Draft-OPD, uses target-assisted rollouts, records anchors, and replays draft proposals there to recover supervision on accepted and rejected tokens, which still involves sequential rollout and verification. SpecOPD's approach is a different strategy for collecting supervision, not evidence that replaying rejected tokens is ineffective. For the target to score many branches at once
SUCKS 0
0
0
Comments
This page shows all existing comments. To add a new comment, open the post in the forum.
No comments yet.