
AI models show systematic errors in breast cancer pathology reporting
Source: bioengineer.org
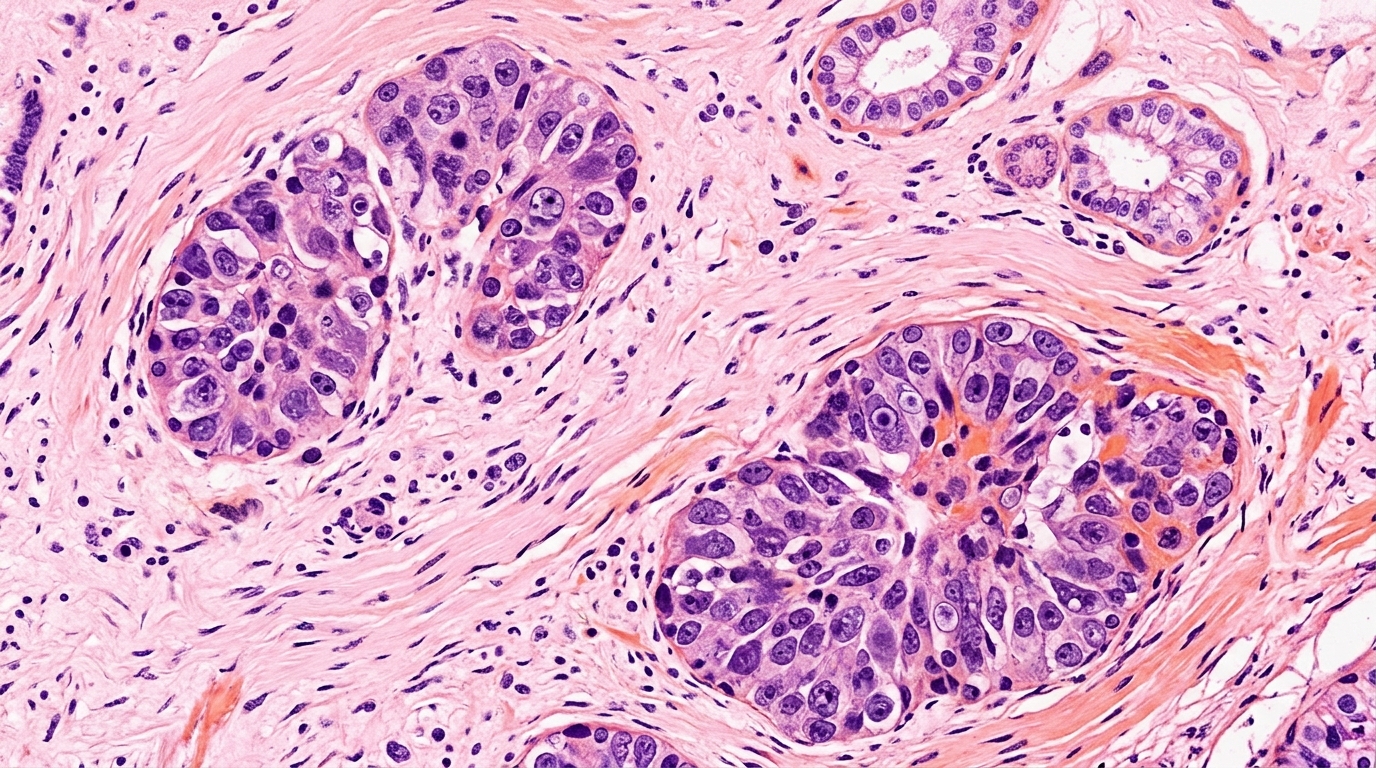
A single-center retrospective paired concordance study published in Breast Cancer Research found that three flagship commercial multimodal large language models—Claude Sonnet 4.6, Gemini 2.5 Pro and GPT-5.5—failed to reach agreement levels sufficient for autonomous extraction of clinically relevant breast pathology features when compared against a board-certified breast pathologist reference in 427 invasive breast cancer cases. Each model received the same overview and 16 H&E tissue tiles per case and the same prompt, and researchers assessed item-level concordance, compared raw and chance-corrected agreement, and characterized error direction. In 111 cases, two pathologists blinded to the report re-read the submitted slide, and image packets given to the models were reviewed separately. No model achieved agreement sufficient to support autonomous extraction of any feature. On blinded review of image packets in 110 cases, lymphovascular invasion was visible in none and perineural invasion in one; Claude and GPT-5.5 reported neither, whereas Gemini reported lymphovascular invasion in 26 packets, none supported by the images. Invasive carcinoma was absent from five packets, for which a Nottingham grade was nevertheless returned in 14 of 15 model-case pairs. Claude ranked highest by raw histological-type concordance at 87.4 percent, yet classified every lobular and micropapillary carcinoma as no-special-type. In an exploratory negative-control analysis against IHC-defined receptor classes, HER2-positive sensitivity was at most 3.6 percent
SUCKS 0
0
0
Comments
This page shows all existing comments. To add a new comment, open the post in the forum.
No comments yet.