
Meet TwIL-8B, webAI's AI Model for Math, Coding, and Reasoning | Hack…
Source: hackernoon.com
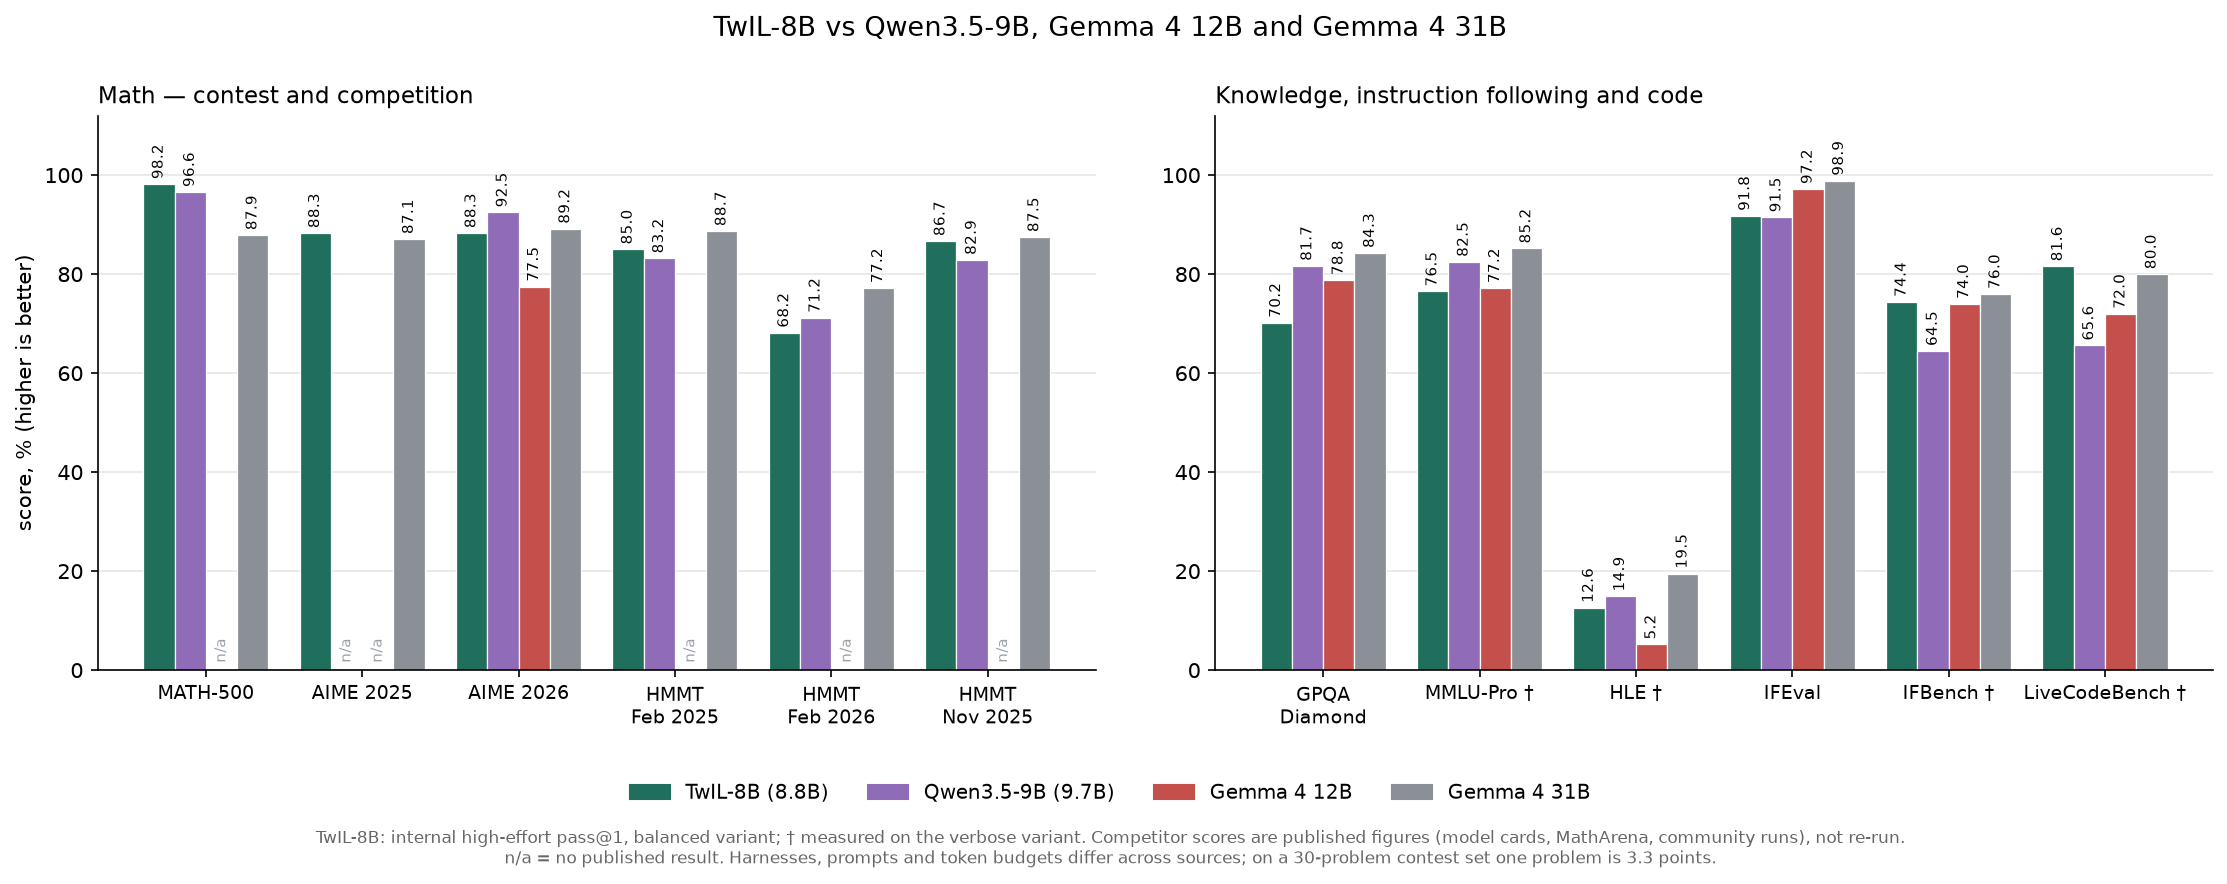
webAI-Official has released TwIL-8B, an 8.79B-parameter English text-generation model post-trained from IBM Granite 4.2 8B for contest mathematics, code, and instruction following, offered in balanced (default) and verbose variants. The supplied benchmark results show strengths in math, code, and instruction following, with weaker results on knowledge-heavy benchmarks; GPQA Diamond is 70.2, and the supplied comparisons show lower scores than Qwen3.5-9B and Gemma 4 31B on GPQA Diamond, MMLU-Pro, and HLE. The balanced variant is intended for general use with shorter reasoning traces, while the verbose variant targets difficult contest-style problems where longer reasoning is acceptable. Against Qwen3.5-9B, the supplied results show TwIL-8B ahead on MATH-500, LiveCodeBench, IFBench, and two of four shared contest sets, while behind on GPQA Diamond, MMLU-Pro, AIME 2026, and HMMT Feb 2026; against Gemma 4 31B, it leads on MATH-500, AIME 2025, and LiveCodeBench but trails on several knowledge, instruction-following, and contest benchmarks. These are source-reported comparisons, not controlled reruns. The model is a Granite decoder-only dense transformer using GraniteForCausalLM with 40 layers, hidden size 409
SUCKS 0
0
0
Comments
This page shows all existing comments. To add a new comment, open the post in the forum.
No comments yet.