
Real-Time Video at Batch Size One | Runway Research
Source: runway.com
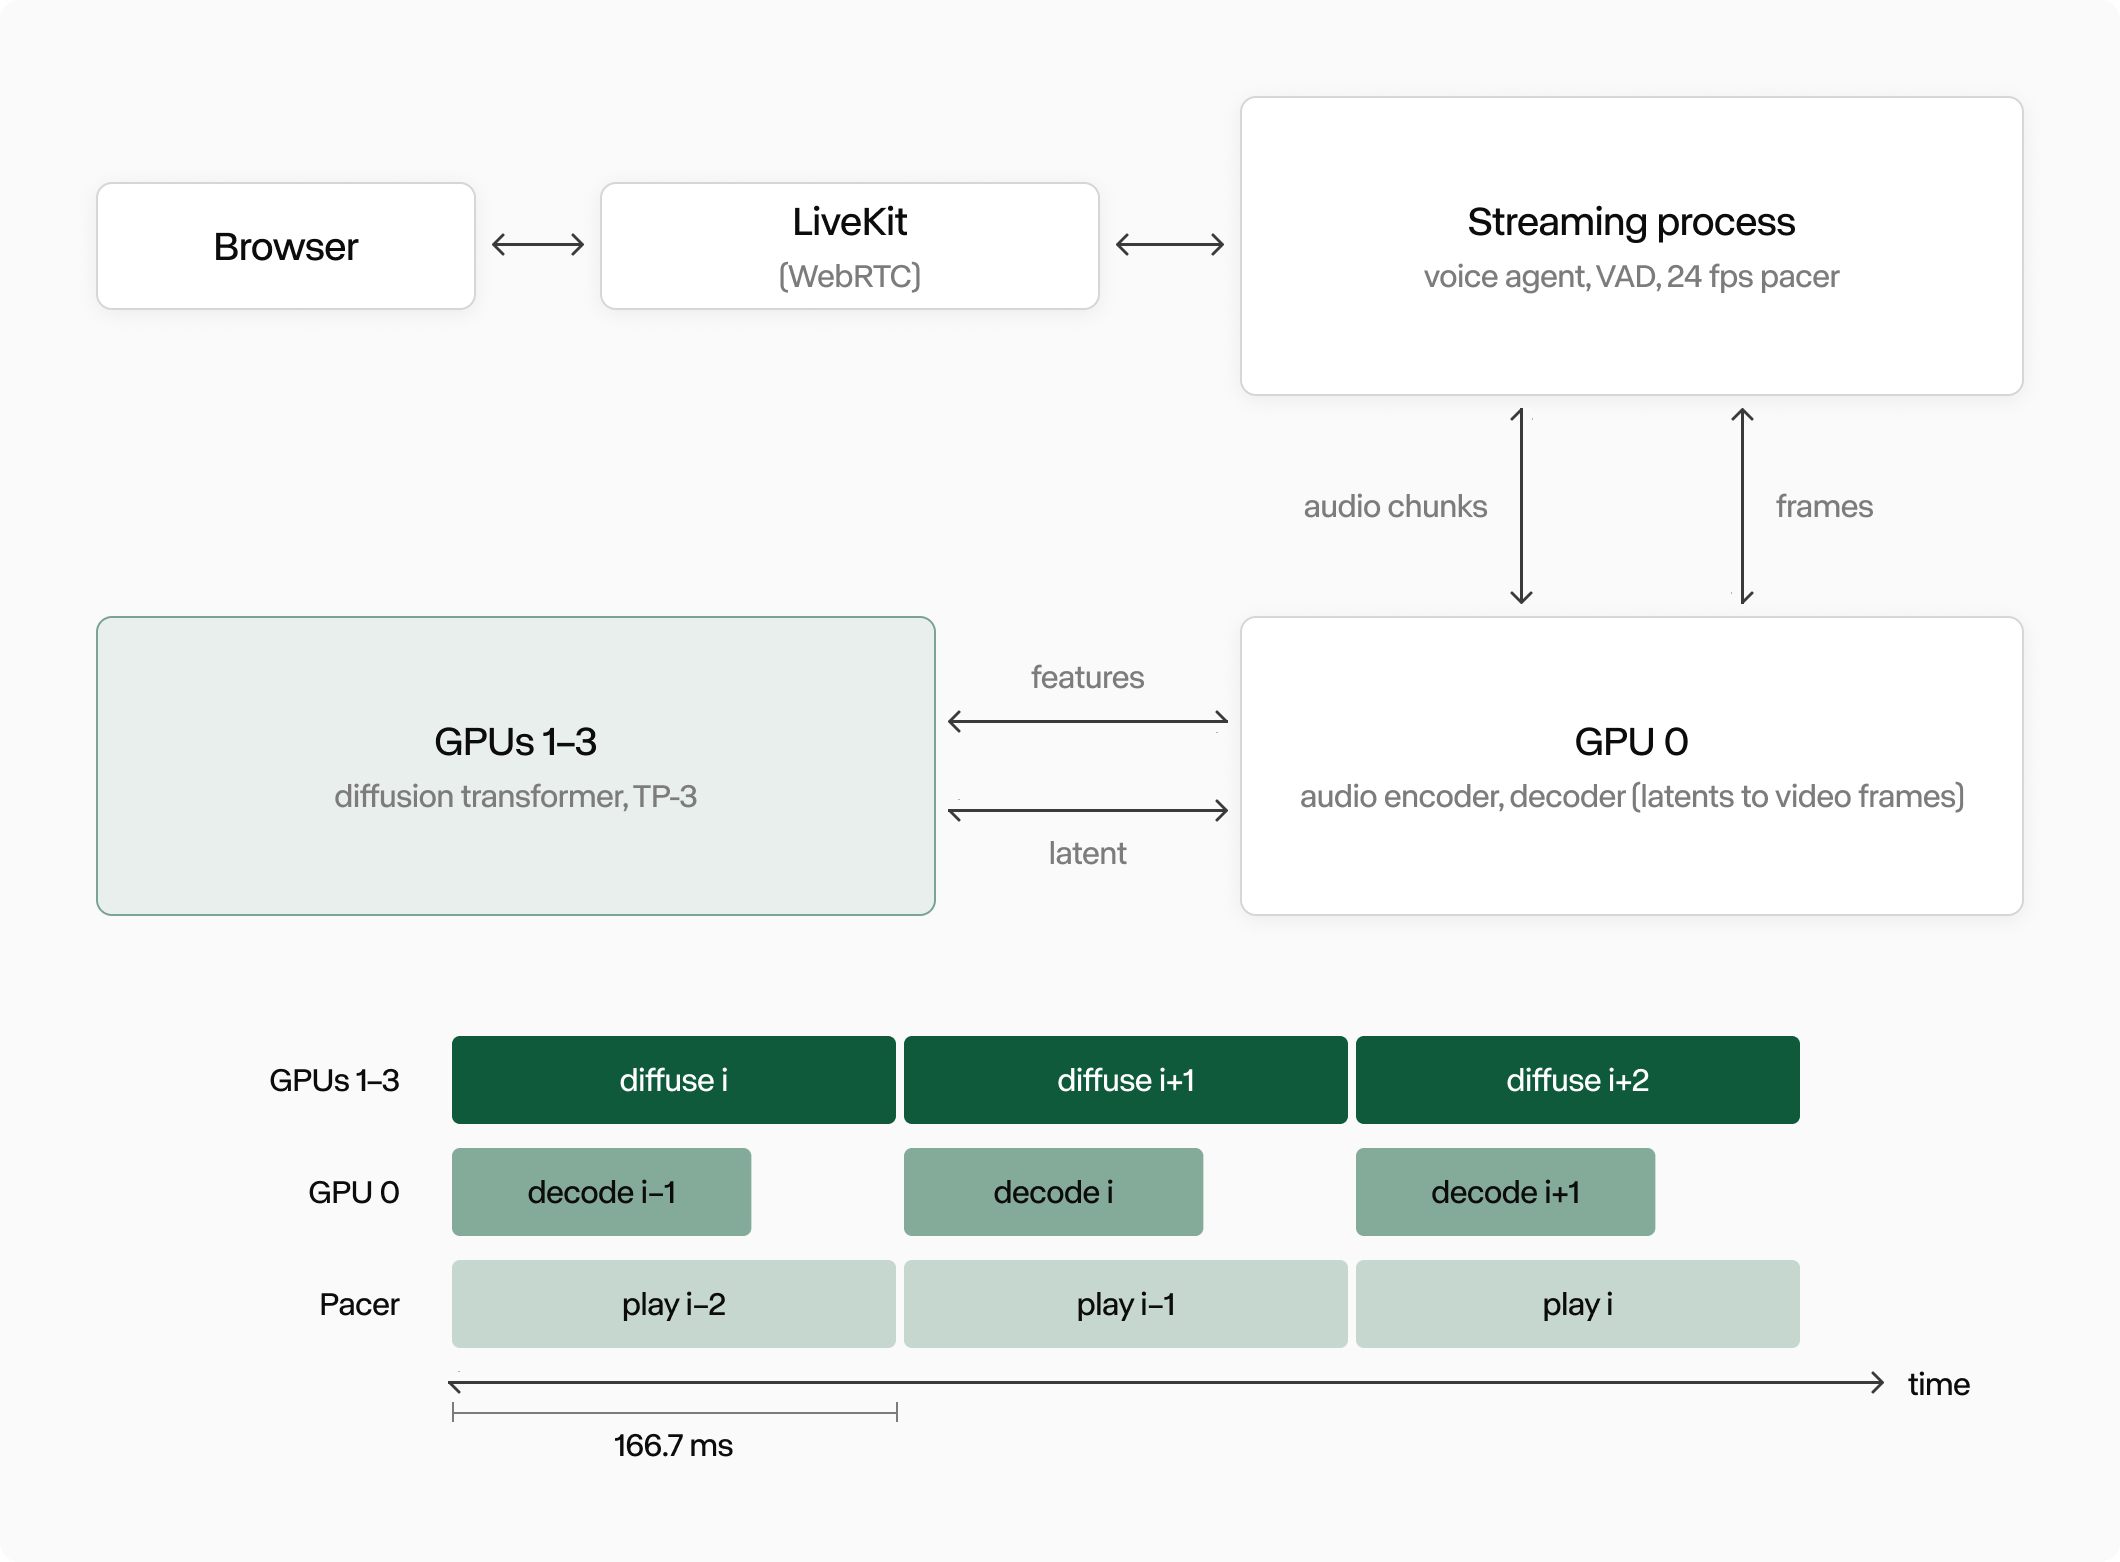
Runway has published research on Runway Characters, a system that turns a single image into a live character users can talk to, powered by a roughly 57B-parameter autoregressive video diffusion transformer. At 24 frames per second (fps), the model must generate a new four-frame chunk of 704x1088 video every 166.7ms for one user at a time for as long as the conversation lasts. Characters launched on eight H100s per session; on four, the launch software took 240.9ms per diffusion step, well over the 166.7ms required. Optimizations cut it to 159.3ms (1.51x faster, 24.5 fps sustained), so each session now runs in real time on four H100s, and a fused communication kernel takes it to 147.4ms (1.63x). In the original step, 29% of GPU time went to reprocessing a mostly unchanged cache in each of 240 attention calls, while attention itself took 6%; doing that work once cut cache upkeep from 69.7ms to 6.2ms per step. Fusing the tensor-parallel all-reduce into the FP8 matrix multiplication hides 54-68% of its time; at production shape the fused call takes 153.8µs against 208.2µs. Across 51 scored clips, mean lip-sync differences were at most 0.03
SUCKS 0
0
0
Comments
This page shows all existing comments. To add a new comment, open the post in the forum.
No comments yet.