
Invisible to the Naked Eye? Tsinghua Researchers Introduce Visual Sou…
Source: eu.36kr.com
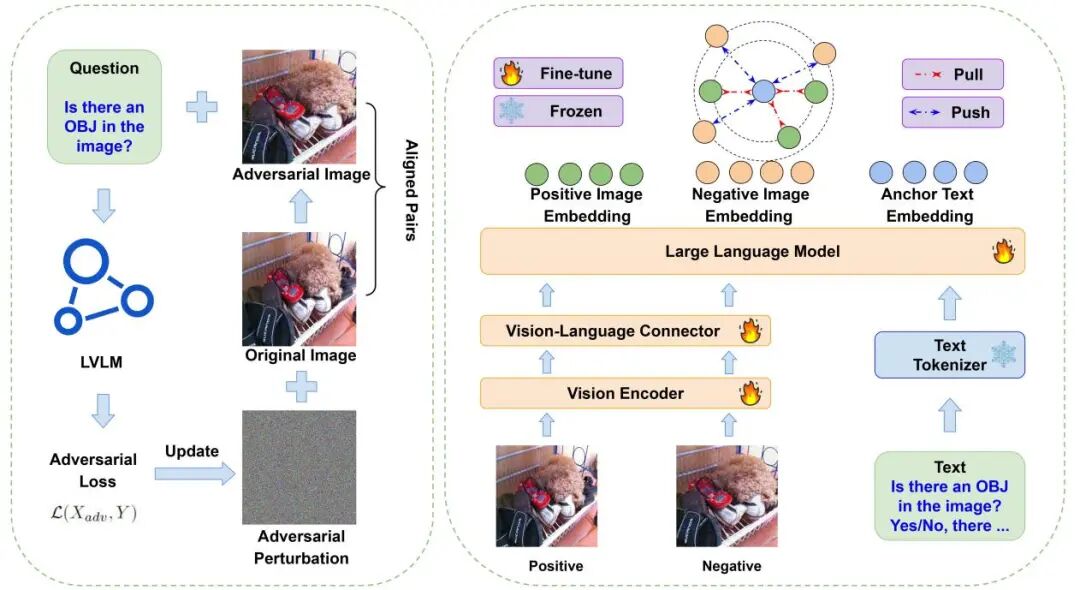
A Tsinghua University research team argues that the mainstream explanation for object hallucination in multimodal large language models—language prior—is incomplete, proposing instead a mechanism rooted in visual feature extraction that emerges when model outputs are very short, such as Yes/No answers. In a paper presented at ACM MM 2026 (the 34th ACM International Conference on Multimedia), the researchers named this visual-origin hallucination and proposed a corresponding solution, ACFT. Experiments show that ACFT uses only 0.9% of the data volume of the COCO dataset, adds no inference overhead, and achieves excellent performance on three models including LLaVA, MiniGPT-4 and Qwen2.5-VL on POPE, MME and four description-level hallucination benchmarks. The paper notes that object hallucination has long been the core obstacle to MLLM reliability, with existing work following the language-prior clue and mitigation methods divided by intervention position, including input-level intervention at the decoding stage by VCD and OPERA, output post-processing via an external grounding module by Woodpecker, and post-training alignment methods such as RLHF and DPO.
SUCKS 0
0
0
Comments
This page shows all existing comments. To add a new comment, open the post in the forum.
No comments yet.